In three lines
- Mk.1, which is PPO plus curiosity (RND) and SimBa, broke through on fishing. Then I spent days adding a memory module, found it did nothing in the real game and threw it all out
- Something had to be checked before comparing structures. Cutting the islands from 8,192 to 2,048, which simply gives four times the updates, turned 8.3 days into 22.5 at the same 20M steps
- The final HyPPO reaches a 26.9-day mean and 79% survival to day 30 over 3 seeds at 40M steps. The anchors I added as our own idea hurt, so they went, and removing HL-Gauss or RND clearly hurt
HyPPO on day 30
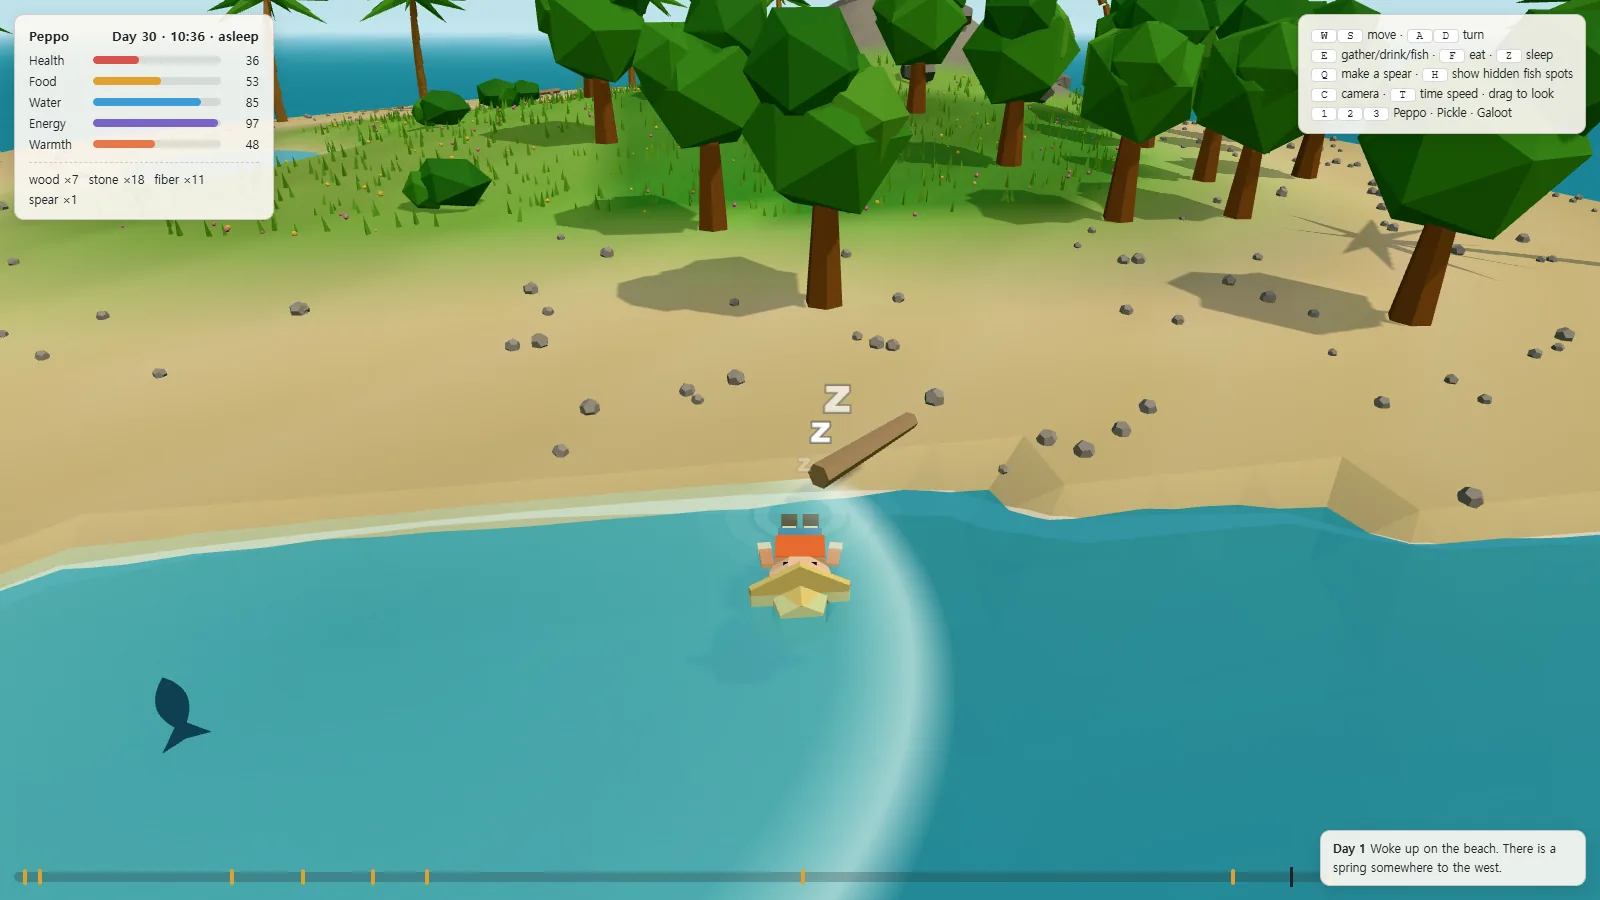
Made by HSL — HyPPO at 40M steps, survival reward only, day 30. Under the 11/1 rules it could still sleep in water (fixed in part 2)
Mk.1: curiosity broke through on fishing
- As planned in part 3, PPO + GRU got a SimBa body, RND curiosity and a Simplicial Embedding (SEM)
- To see what was actually working, I also ran versions with one part removed
| Condition | Mean survival | Reach day 30 | Fish per life |
|---|---|---|---|
| PPO + GRU | 10.9 days | 0% | 0.0 |
| Mk.1 | 21.6 days | 26.3% | 17.2 |
| Mk.1 − RND | 14.2 days | 0% | 0.2 |
| Mk.1 − SimBa | 14.7 days | 0% | 1.3 |
| Mk.1 − SEM | 21.6 days | 32.9% | 14.3 |
60M steps, mean of 3 seeds, evaluated on 1,024 islands, 10/30 (runs/p1/results.jsonl)
- Without RND or SimBa, catches nearly vanished (17.2 fish per life down to 0.2 and 1.3). With Mk.1, 75 to 94% of lives per seed fished
- Without SEM, the mean stayed the same. There was no evidence it was needed
- Where the parts come from: SimBa · RND · Simplicial Embedding
Days spent bolting on memory
- The next goal was a general memory, not one for this game alone: live several times on the same island and use what an earlier life found out
- I built a “fact” memory that stores actions and their results, and a short test of two lives. The first life finds out which food is the local speciality, and the second has to choose it
- It passed that test
| Food choice accuracy in life 2 | Value |
|---|---|
| Fact memory | 0.977 |
| Memory read set to zero | 0.492 |
| Memory contents deliberately swapped | Followed the swapped memory 0.978 |
| Mk.1, no memory | 0.517 |
Seed 0, 2,048 trials, 10/30 (runs/pr3/results.jsonl). Fact accuracy on seeds 1 and 2: 0.985, 0.956
- That proves the memory really changes decisions
- But over 5 lives of the real game it did nothing
| 5-life evaluation, same rules | Mean survival | Life 1 → life 5 |
|---|---|---|
| Mk.1 (no memory) | 8.95 days | |
| Fact memory (with auxiliary loss) | 4.38 days | 4.41 → 4.30 |
| Fact memory (no auxiliary loss) | 12.47 days | 12.69 → 12.39 |
| The model above, memory read erased | 12.40 days | 12.38 → 12.54 |
20M steps, trained on 8,192 islands, one seed, evaluated on 512 islands, 10/31 (runs/dx_trial_*/eval.json)
- Erasing it changes nothing, and later lives are no better. In the real game the policy did not use the memory
- I also chased a wrong lead. I stuck with a 3-day plateau in the general game all the way to 60M steps (fact 3.37 days, no memory 3.17), but that came from training settings I had changed for the test. With the earlier settings the results looked like the table above
The real cause was the update count
- More islands pile up steps faster, but they also raise the steps needed for each learning update
- 8,192 islands × a rollout of 64 means only 38 PPO updates in 20M steps. Every structure comparison so far had been looking at early training, where a new part always looks like a burden
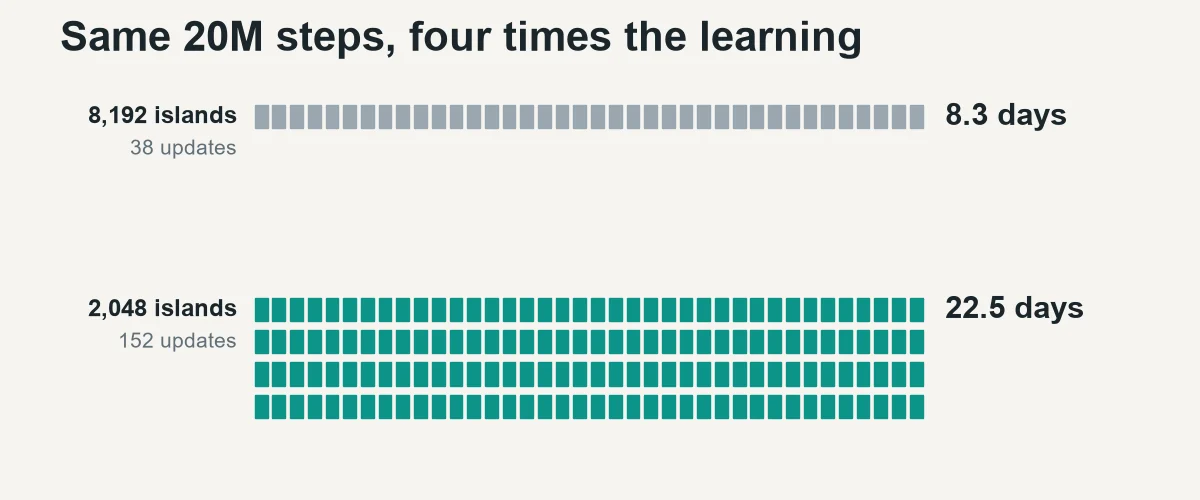
Made by HSL — Mk.1, 20M steps, evaluated on 512 islands, one seed, 10/31
| Islands at once | Updates | Mean survival | Reach day 30 | Training time |
|---|---|---|---|---|
| 8,192 | 38 | 8.3 days | 0% | About 5 min |
| 2,048 | 152 | 22.5 days | 34.0% | 9.9 min |
| 1,024 | 305 | 19.8 days | 47.7% | 17.8 min |
runs/dx_plain_mk1, upd_e2048, upd_e1024 (eval.json, log.json). The 8,192 time is calculated from that run’s speed, about 66,000 steps per second
- I made 2,048 the new default and measured memory again, fairly
- Spatial memory: over 4 seeds at 20M steps, GRU 18.5 days, GRU + spatial memory 19.2, with the read erased 18.4. That is inside the spread between seeds
- On an island where the fishing spots move every time, one seed at 40M steps gave GRU 25.5 days and spatial memory 20.1
- So every memory module went, and the core stayed a GRU
HyPPO: only the sphere GRU stayed
- Two problems were left: whether a seed learned to fish at all, and losing at 40M the fishing learned by 30M. Mk.1’s seed 0 fell from 27.2 days to 19.9 and from 20.4 fish per life to 6.7
- I consulted four AIs on the structure (Fable, Astra, Argon, Opus), under one condition I had set: it had to be structure, not a training trick or reward design
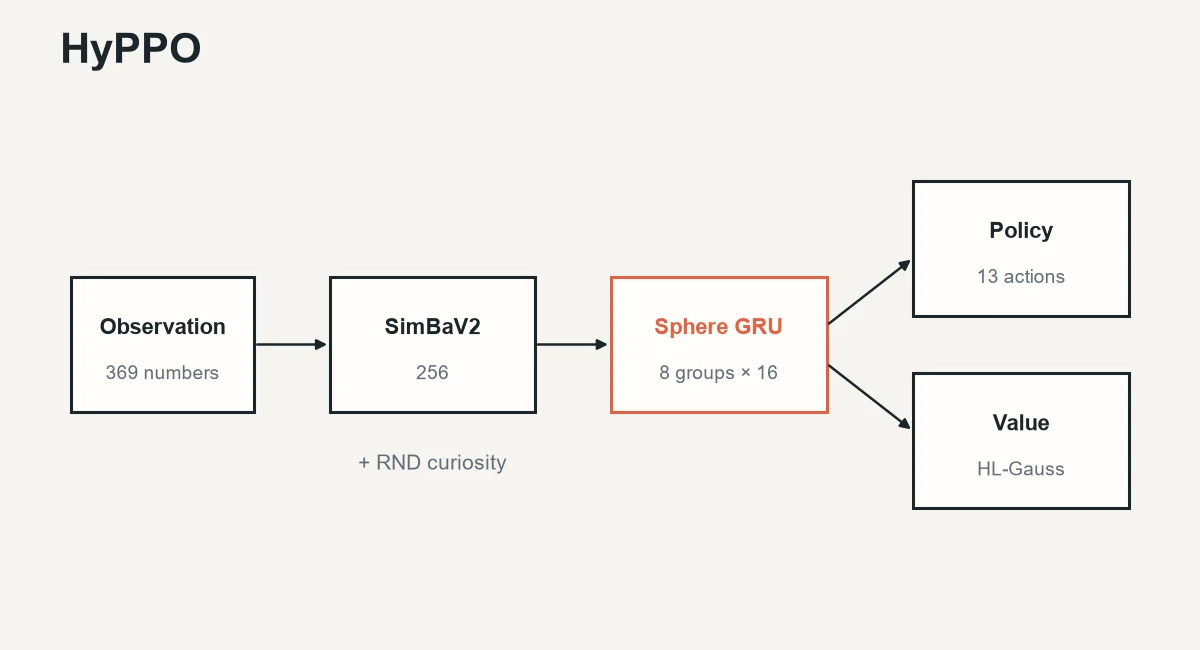
Made by HSL — the HyPPO structure
- The body is SimBaV2, the value head is HL-Gauss, and the curiosity is RND. All existing parts
- What I built is the core, a group-hyperspherical GRU. Its state is 8 unit vectors of 16 dimensions, and the GRU’s blend happens on those spheres
r, z = torch.sigmoid((gx[:, :2 * H] + self.u_rz(h)) * gs[:2 * H] + self.bias[:2 * H]).chunk(2, -1)
c = torch.tanh((gx[:, 2 * H:] + self.u_c(r * h)) * gs[2 * H:] + self.bias[2 * H:])
c = F.normalize(c.view(-1, G, D), dim=-1, eps=1e-3)
hv, zg = h.view(-1, G, D), z.view(-1, G, D)
hn = F.normalize(hv + zg * (c - hv), dim=-1, eps=1e-3)
From SphereGRU.step in train/nets.py (anchor part left out)
- The key idea at first was anchors on top of that: 8 learned unit vectors per group that pull the state toward them, Fable’s proposal for keeping the fishing habit from being erased
- I ran to 40M steps and removed one thing at a time from the top. Only the anchors hurt
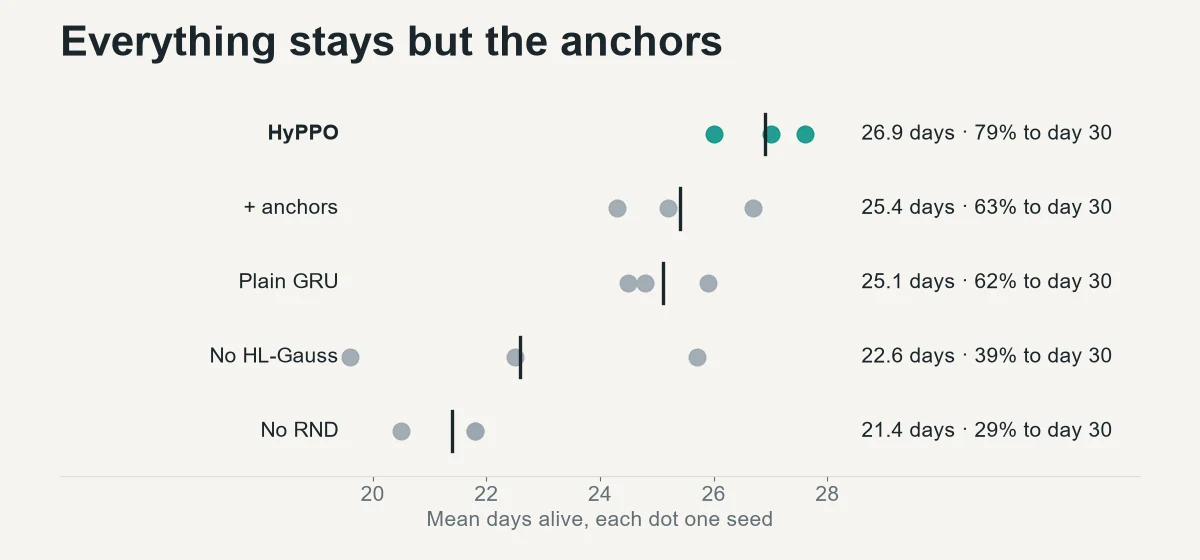
Made by HSL — 40M steps, 3 seeds, evaluated on 512 islands, 11/1 (runs/mk2/summary.md). The no-HL-Gauss and no-RND runs were removed from the anchored version
| Condition | Mean survival | Reach day 30 | Fish per life | Steps per second |
|---|---|---|---|---|
| HyPPO (no anchors) | 26.9 ± 0.8 days | 78.7% | 18.1 | 31,000 |
| + anchors | 25.4 ± 1.2 days | 62.6% | 14.4 | 28,000 |
| Plain GRU | 25.1 ± 0.7 days | 61.5% | 14.1 | |
| No HL-Gauss | 22.6 ± 3.0 days | 39.0% | 14.5 | |
| No RND | 21.4 ± 0.8 days | 29.4% | 8.9 | |
| Mk.1 (same islands and steps) | 23.0 ± 3.7 days | 44.9% | 13.7 |
runs/mk2/summary.md, runs/m2/summary.md. Steps per second from seed 0’s training log
- So the version without anchors became final, named HyPPO (Hyperspherical PPO)
- The limits are clear too. The gap between sphere GRU and plain GRU is 1.8 days at 40M but gone at 20M, 24.6 against 24.7. With 3 seeds and one island, this is no basis for a paper-level claim
- I did not run the PPO + GRU baseline at the same island count and 40M steps
- The collapse is not fully gone either. The 3-seed mean held from 26.1 days at 30M to 26.9 at 40M, but when I later trained Peppo, the training-log mean reached 28.9 days, dropped to 16.1, and ended at 24.4
If I did it again
- Check the update count before comparing structures. That cost me days
- Do not trust a passed test environment. The memory scored 0.977 on the short test and did nothing in the real game
- Judge ideas by removing them from the top. Five conditions at 40M steps, a few hours, were enough to rule out the anchors I had worked hard on
- Next part: the three characters living with this brain