One-Line Take
Calling a model that scores 65 on the AA index "5.2" looks like leaving the 5.5 slot open. Something bigger is coming, and Anthropic has yet to disappoint (author's view)
A 65 on the Index and the Version Moved by 0.1
- Anthropic released Claude Fable 5.2 and Mythos 5.2 on November 9 (Anthropic)
- They are the same model; Fable is the one with cyber and biology safeguards that anyone can use
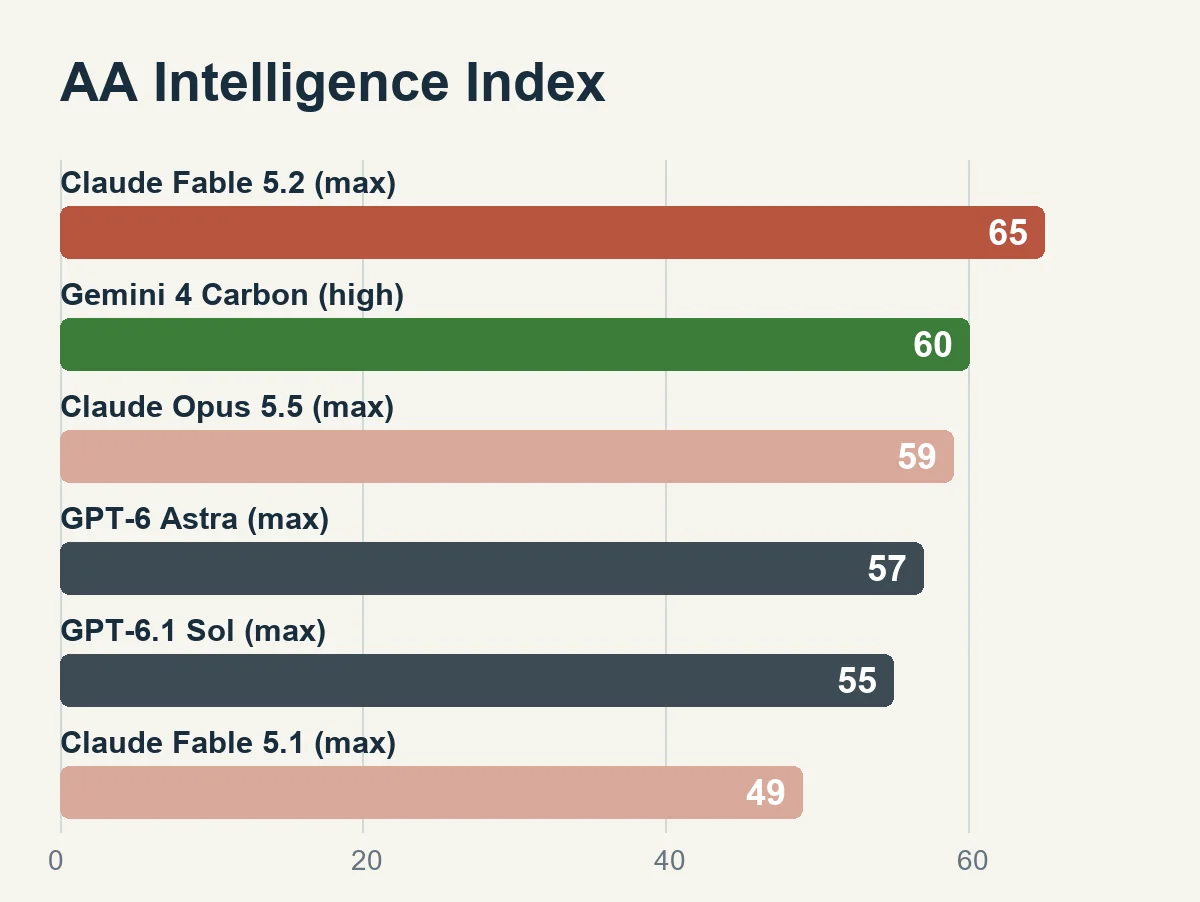
- Fable 5.2 at max effort ranks first on the Artificial Analysis (AA) Intelligence Index with 65 (AA leaderboard)
- The index is a composite, 25% each of knowledge work, coding, science and general ability (AA methodology)
Made by HSL — AA leaderboard and Fable 5.1 page, checked November 10, 2026
- Max against max, that is 16 points above Fable 5.1's 49
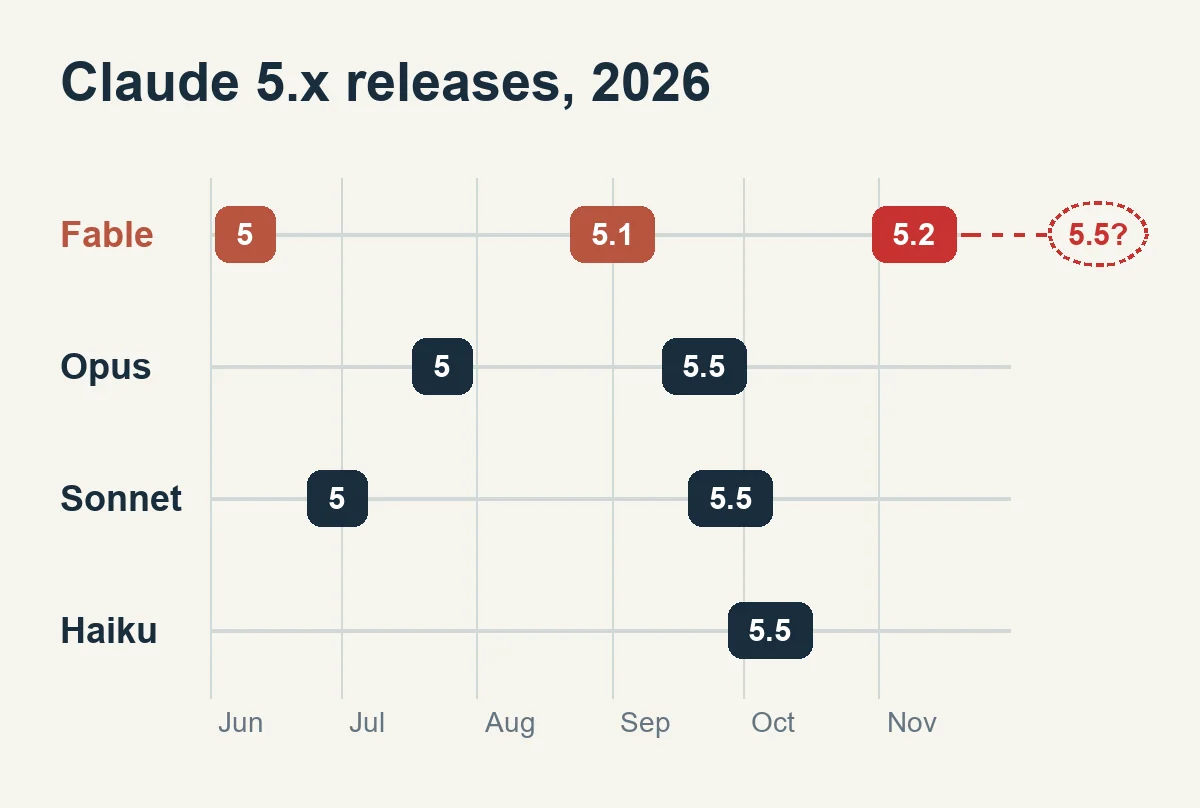
- The version number went from 5.1 to 5.2
- The lineup makes it stranger: Opus, Sonnet and Haiku are already at 5.5, and only Fable, the top tier, sits at 5.2
Made by HSL — Anthropic model docs and each launch post. The 5.5? is the author's guess, not a published schedule
- A top model numbered below the tiers under it looks like 5.5 is being saved on purpose (author's view)
- There is a counterargument: Anthropic has never explained the 5.2, and 5, 5.1, 5.2 may simply be numbers in sequence
- I also found no rule saying version numbers must grow with scores
I Think 5.5 Already Exists Inside
- If a 65 still did not earn the name 5.5, there may be something else that does (author's view)
- That a stronger model exists inside is something Anthropic wrote itself
- This system card reports, for the first time, scores for an unreleased internal research model "somewhat more capable" than Mythos 5.2 (system card, section 2.3)
| Model | AECI score | Status |
|---|---|---|
| Mythos 5.1 | 172.62 | Released |
| Opus 5.5 | 174.78 | Released |
| Mythos 5.2 (same model as Fable 5.2) | 177.12 | Released |
| Internal research model | 178.78 | Unreleased |
AECI is Anthropic's own capability index. Source: system card table 2.3.5.3.A
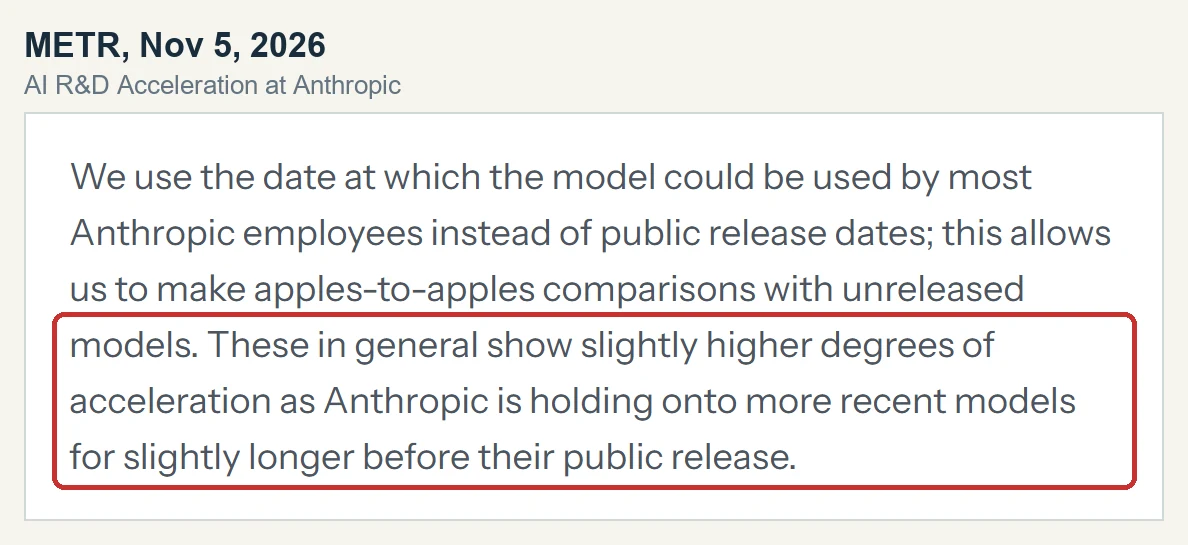
- Outside evaluator METR also wrote that Anthropic is holding recent models slightly longer before release
Source: METR — Independent Assessment of AI R&D Acceleration at Anthropic, November 5, 2026, red outline added by HSL
- METR's internal-only Model 4 finished training in September–October and scores 178.6 on AECI
- That is almost the same as the system card's internal model, so they look like one model (author's estimate)
- The full METR report also forecast a future model, and that part is redacted
- Anthropic's IPO filing says it does not release every model it develops for general use (S-1)
- Nothing shows this internal model is a 5.5, though; the system card gives no name and no release plan
- The gap is also small at 1.66 points with overlapping error ranges, below the 2.34 points from Opus 5.5 to Mythos 5.2
- The Fable 5.5 testing rumor from October may also have been an early look at today's 5.2
I'm Betting on Something Bigger
- Something bigger is coming, and Anthropic has always delivered on expectations (author's view)
- This release added 16 points while cutting the list price from $10 / $50 to $8 / $40 per million tokens
- Anthropic also says output is up to 30% faster than 5.1, which is the maker's figure
- METR estimates Anthropic's benchmark progress has run 1.9x faster since October 2025, with a 95% interval of 1.5–2.8x
- It attributes most of that speedup to Anthropic's own use of AI in research
- Anthropic also says it deliberately held some abilities that directly speed up AI development at about Opus 5.5's level during training
- METR gives reasons for caution too: most of the evidence it found most informative is redacted, so the public cannot judge it directly
- METR also says benchmark gains may overstate real-world gains
They Can't Catch Up Anyway, So It Comes Out Bit by Bit
Saving the rocket
- Rivals can't catch up anyway, so Anthropic seems to keep unreleased models back and let them out a little at a time (author's view)
- Gemini 4 Carbon took first place on October 28 with 59, and a 0.1 version bump took it back 12 days later (Google)
- Anthropic's CEO has written that how far pacing can go is limited by the lead US companies hold (Dario Amodei)
- That essay is about China, though, and it says nothing about staged releases
- "Can't catch up" also has counterexamples
| Item | Fable 5.2 | Best rival | Source |
|---|---|---|---|
| AA index | 65 (max) | 60 (Carbon high) | AA |
| AA cost per task | $26.54 | $7.76 (Carbon high) | AA |
| FrontierCode 2.0 coding | 49.1% | 42.8% (GPT-6 Astra) | Anthropic |
| Chartography chart reading | 73.4% | 72.5% (Carbon) | Anthropic |
| AutomationBench business workflows | 51.4% | 53.9% (Carbon) | Anthropic |
- Carbon leads on business workflows, and chart reading is 0.9 points apart
- At high effort Fable scores 62, two points above Carbon
- The 65 is expensive: about 3.4 times Carbon's cost per task and about twice Fable 5.1 max's $12.99
- Nothing shows comfort is the only reason either; the S-1 says Anthropic has delayed or limited releases for safety
So What's Next?
- First, watch the next number. A 5.3 would badly weaken my reading, and a 5.5 or 6 would support it
- Timing can only be calculated: 5 to 5.1 took 84 days and 5.1 to 5.2 took 69
- The same gaps would land between January 17 and February 1, 2027, which is not an official date
- Second, watch the AA score. If this picture is right, the next Fable should jump well past 65
- Third, watch rivals. If this picture is right, a new Anthropic model should follow soon whenever Google or OpenAI takes first place
- Fable in our AI stock duel has moved to 5.2 too, and 5.2 makes the calls from the November 14 weekly meeting
Q&A (Field Notes)
- Q. Should I switch to 5.2 right now?
- Anthropic itself recommends starting most coding and knowledge work on Opus 5.5
- Medium, the default in the apps and Claude Code, scores 56 on AA, so you do not get the 65 by default
- Q. Isn't Mythos 5.2 the hidden 5.5?
- No. It is the same model as Fable 5.2 with different safeguards and access
- Q. Can I use it on a subscription?
- Yes. Paid plans that include Fable get extra usage during launch week
- Pro and standard Team seats can spend up to 50% of their weekly limit on Fable